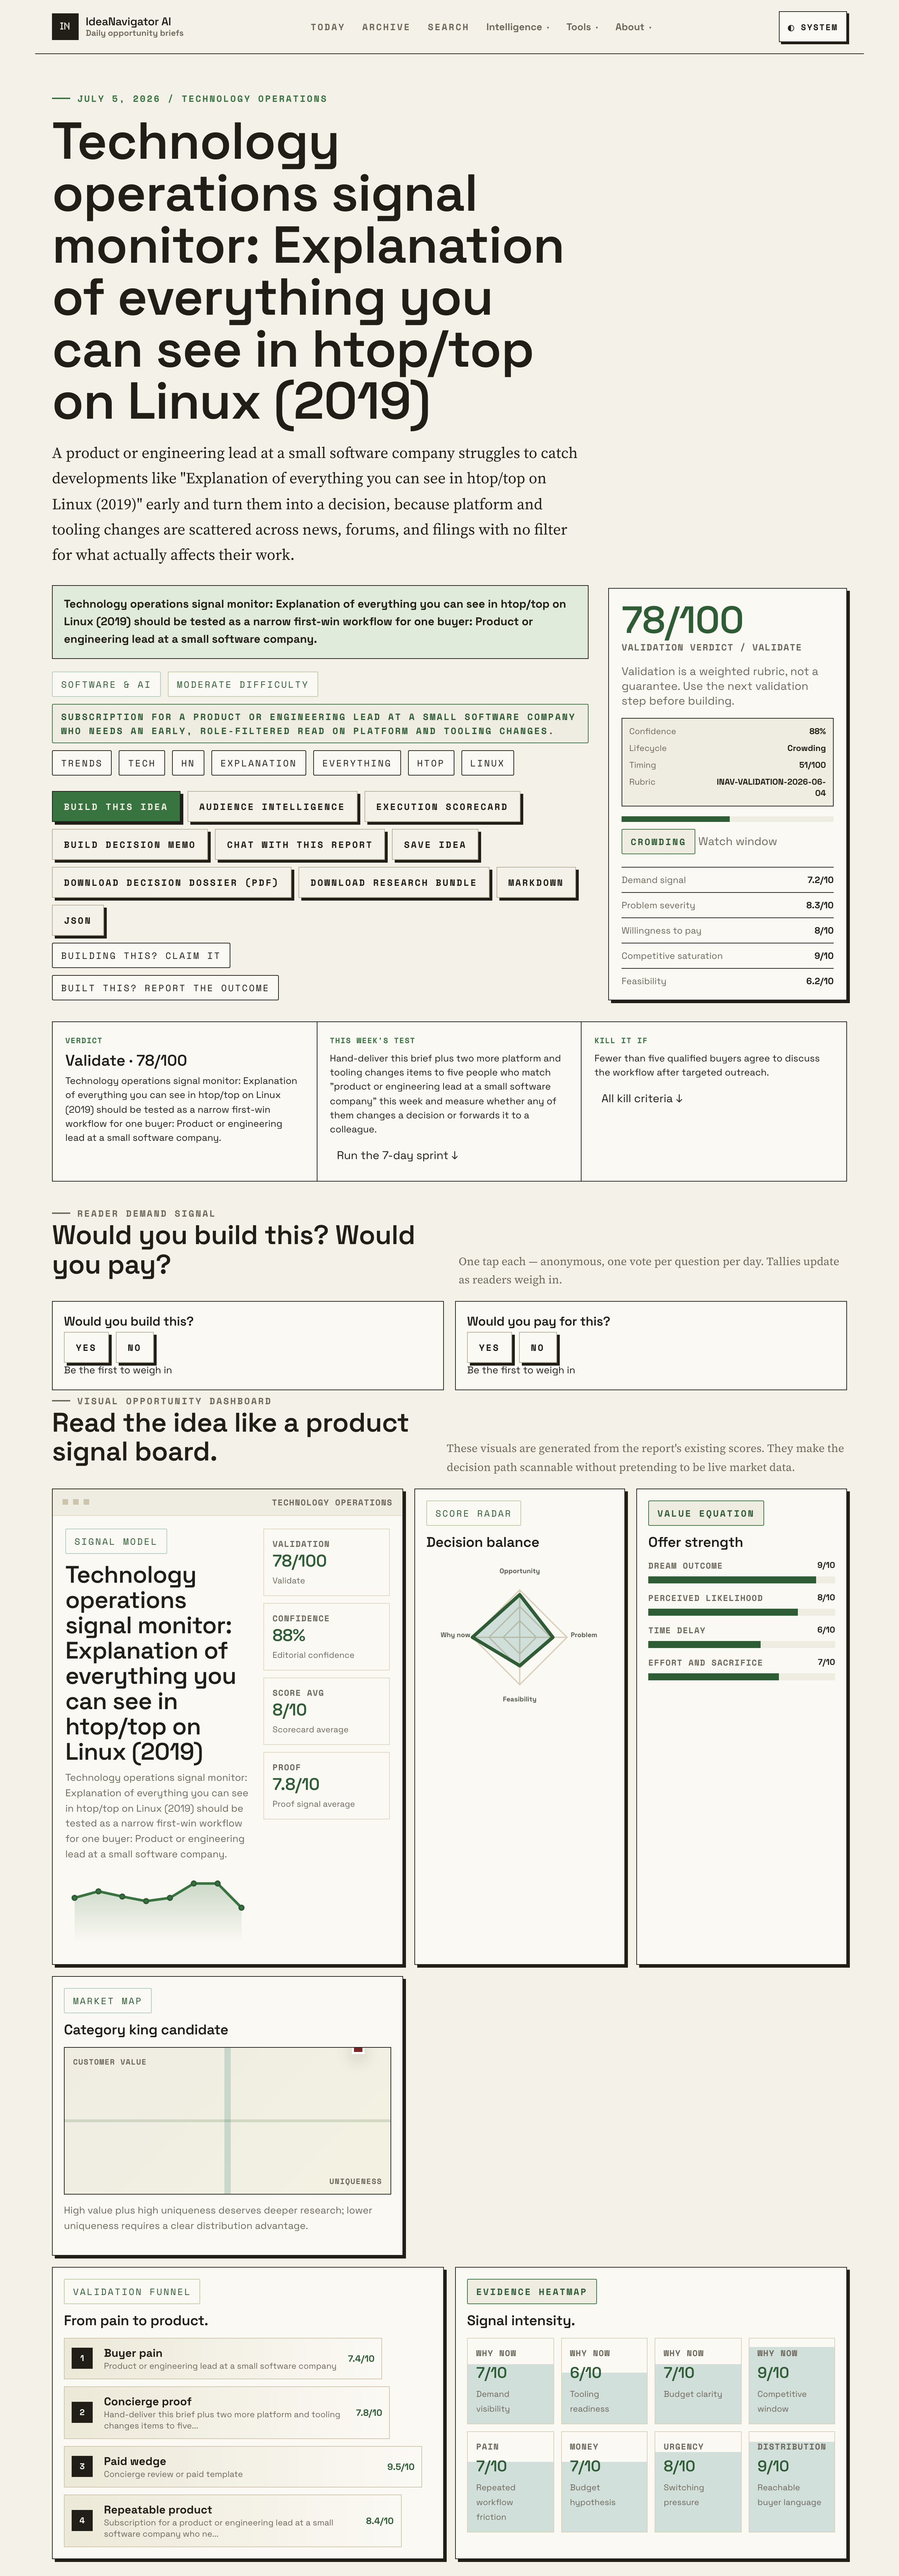
📊 Full opportunity report: Technology Operations Signal Monitor: Explanation Of Everything You Can See In Htop/top On Linux (2019) on IdeaNavigator AI — validation score, market gap, and execution plan.
TL;DR
This article explains what is visible in Linux system monitoring tools htop and top. It clarifies how these tools help small software teams understand system health and why accurate interpretation matters.
Linux system monitoring tools htop and top display a range of real-time system data that helps engineers understand server health and performance. This guide clarifies what each element in these tools represents, providing essential context for product or engineering leads to make informed decisions based on system metrics.
Both htop and top are command-line utilities used to monitor Linux system resources, including CPU, memory, and process activity. They present data in a structured, real-time interface, with htop offering a more user-friendly, color-coded display compared to top’s simpler output.
The core information visible includes CPU utilization, memory and swap usage, load averages, and detailed process lists. CPU usage is broken down into user, system, and idle times, indicating how much processing power is allocated to user applications versus kernel operations or idle states. Memory metrics display total, used, free, and cached memory, helping identify resource bottlenecks. Load averages show the number of processes waiting for CPU time over 1, 5, and 15-minute intervals, giving a snapshot of system load.
Process lists in both tools include process IDs, user ownership, CPU and memory consumption, and command names. This enables engineers to identify resource-heavy processes quickly. htop enhances this with sortable columns, color coding, and interactive features, making it easier to filter and prioritize processes.
Understanding these metrics allows product and engineering leads to detect early signs of system strain, plan capacity, and troubleshoot performance issues. For example, sustained high CPU or memory usage may indicate a need for resource scaling or process optimization.
Why Accurate Interpretation of htop and top Data Matters
Proper understanding of what is displayed in htop and top is critical for small software teams managing Linux servers. Accurate interpretation helps identify system bottlenecks, prevent outages, and optimize performance, ensuring reliable service delivery. Misreading these metrics could lead to unnecessary interventions or overlooked issues, impacting application stability and user experience. As platform and tooling updates evolve rapidly, role-specific insights like these enable product and engineering leads to react swiftly and effectively, maintaining system health without unnecessary disruption.
Linux system monitoring tools htop
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Background on Linux System Monitoring Tools
Since their development, top has been a standard Linux utility for real-time process monitoring, introduced in early Unix systems. Htop, a more recent, enhanced version, offers a more interactive and visually intuitive interface. Both tools are widely used in server management, performance tuning, and troubleshooting.
Over the past decade, these tools have evolved with added features like color coding, process filtering, and customizable displays. Despite this, many users still lack a clear understanding of what each metric signifies, which can lead to misinterpretation of system health. The recent surge in platform updates and tooling changes makes it more important than ever for engineers to understand what they see in these tools, especially in fast-moving environments where early detection of issues is vital.
Prior to this, many teams relied on basic knowledge, but current developments demand a more nuanced understanding to interpret the complex data accurately and act decisively.
command line server monitoring utilities
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Current Gaps in Understanding and Tool Usage
While the basic metrics in htop and top are well-documented, there remains uncertainty about how best to interpret complex or borderline data, especially in rapidly changing environments. It is not yet clear how many engineers fully understand the nuances of load averages versus CPU utilization or how they correlate with actual performance issues. Additionally, the impact of recent platform updates on the display and interpretation of these metrics is still emerging, with some reports indicating changes in default views or added features that may confuse users.
CPU and memory usage monitor for Linux
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps for Better System Monitoring Practices
Product and engineering leads should focus on training and documentation to improve understanding of htop and top metrics. Development of role-specific briefs and decision-making guides could enhance early detection of issues. Additionally, monitoring tool updates and community feedback will help clarify how new features or changes influence interpretation. Future efforts may include integrating these tools with automated alerting systems to reduce manual oversight and improve response times to system anomalies.
As an affiliate, we earn on qualifying purchases.
Key Questions
What are the key metrics shown in htop and top?
The key metrics include CPU utilization (user, system, idle), memory usage (total, used, free, cached), load averages, and the list of active processes with their resource consumption.
How does htop differ from top?
Htop offers a more interactive, color-coded, and sortable interface, making it easier to interpret and manage processes compared to the simpler, text-based top utility.
Why is understanding these tools important for small software teams?
Accurate interpretation allows teams to detect system issues early, optimize performance, and avoid outages, which is critical for maintaining service reliability and user satisfaction.
Are there common misunderstandings about these metrics?
Yes, many users confuse load averages with CPU utilization or misinterpret cached memory as unavailable memory, leading to incorrect troubleshooting decisions.
What should teams do to improve their understanding?
Training sessions, detailed documentation, and role-specific guides can help teams better interpret metrics and respond appropriately to system signals.
Source: IdeaNavigator AI